Beijing Yizhuang Humanoid Robot Research Institute
北人–北大联合实验室 · Data / Infra Lead
4D priors for world models, unified-model scaling, embodied benchmarks, robot and ego data pipelines, and deployment infrastructure for humanoid platforms.
FROM RESEARCH TO DEPLOYMENT
2026.02–2026.10
Beijing Yizhuang Humanoid Robot Research Institute北人–北大联合实验室 · Data / Infra Lead 4D priors for world models, unified-model scaling, embodied benchmarks, robot and ego data pipelines, and deployment infrastructure for humanoid platforms. 2025.12–2026.02
Beijing Academy of Artificial IntelligenceEmbodied intelligence · Multimodal research Improved visual representations in VLA models for spatial understanding, then transferred the work to VLN and quadruped-robot deployment. 2024.06–2025.12
Xiaomi MotorsAutonomous driving VLA · Future Star intern Planning models, controllable video synthesis, automatic labeling, large-scale clips, FP8 quantization, and SIL release workflows. 2024.01–2024.06
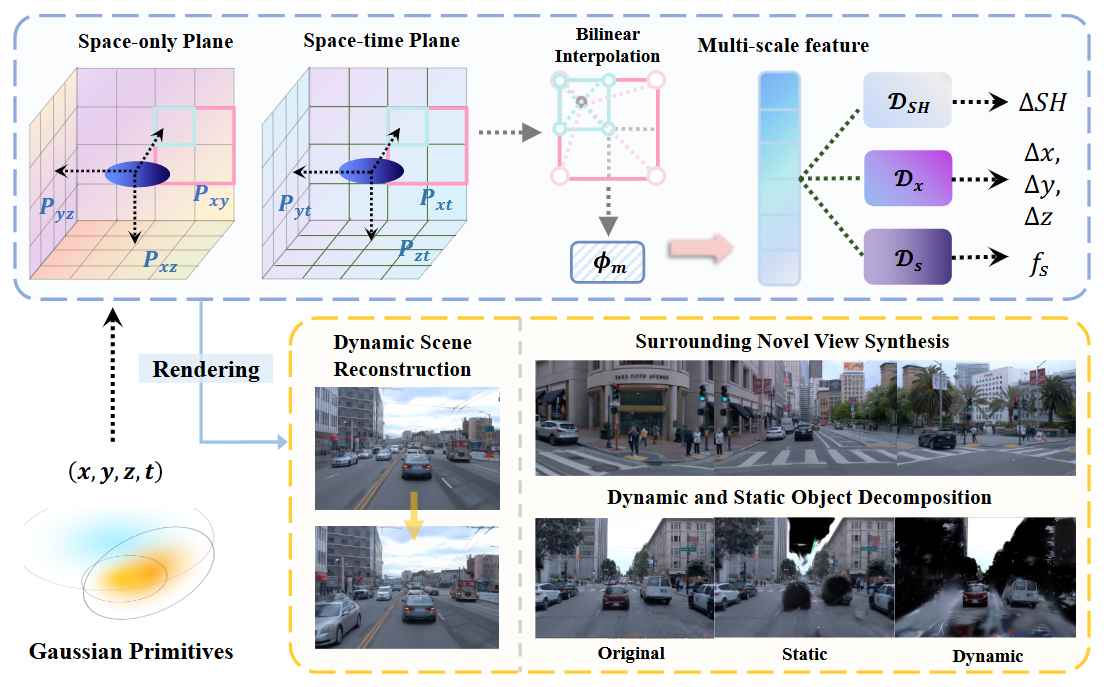
NIOAutonomous driving world models Street-scene 4D reconstruction and generative world models, including EMD, S3Gaussian, SparseStreet, and a 4,000+ clip corner-case pipeline. 2023.07–2024.01
AMDEnd-to-end autonomous driving Cross-domain and open-world 3D detection, with research integrated into production-facing autonomous-driving pipelines. A RESEARCHER'S NOTE
The hard part of an agentic robot is not adding another module. It is giving perception, memory, prediction, and action a shared clock. I study the interfaces that make this loop trainable: data with state, world models with foresight, and policies that turn uncertainty into action.
01 Data with state
02 Models with foresight
03 Action under uncertainty
SELECTED PUBLICATIONS
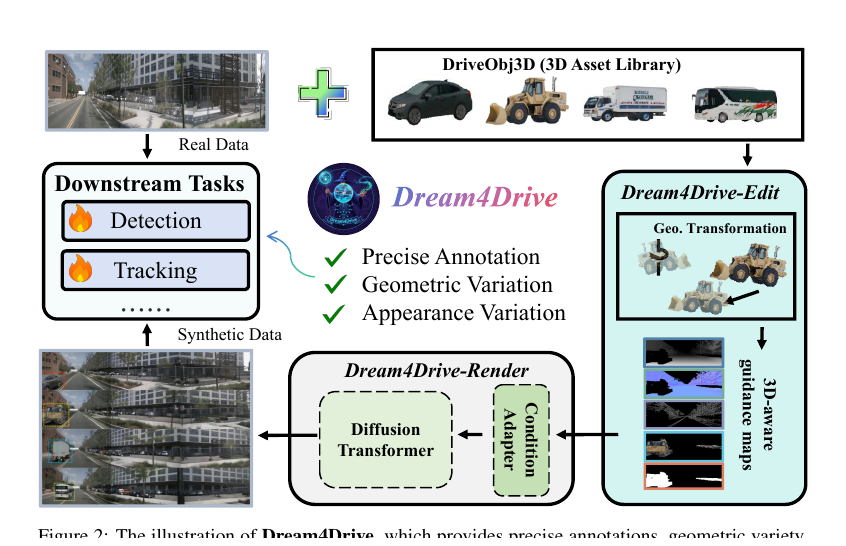
Rethinking Driving World ModelDream4Drive turns 3D-aware world-model editing into controllable synthetic data for downstream perception.
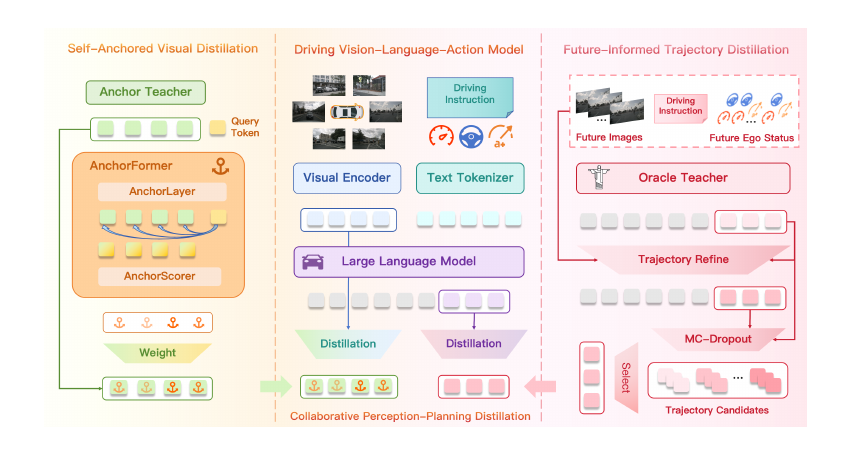
EvoDriveVLACollaborative perception-planning distillation for stronger driving VLA models.
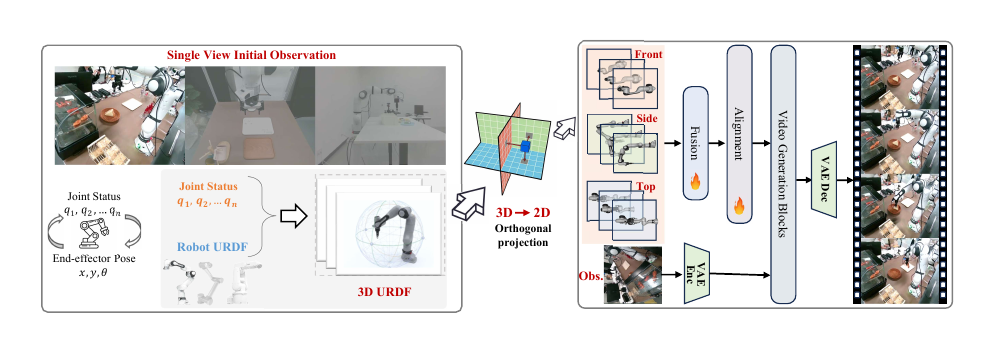
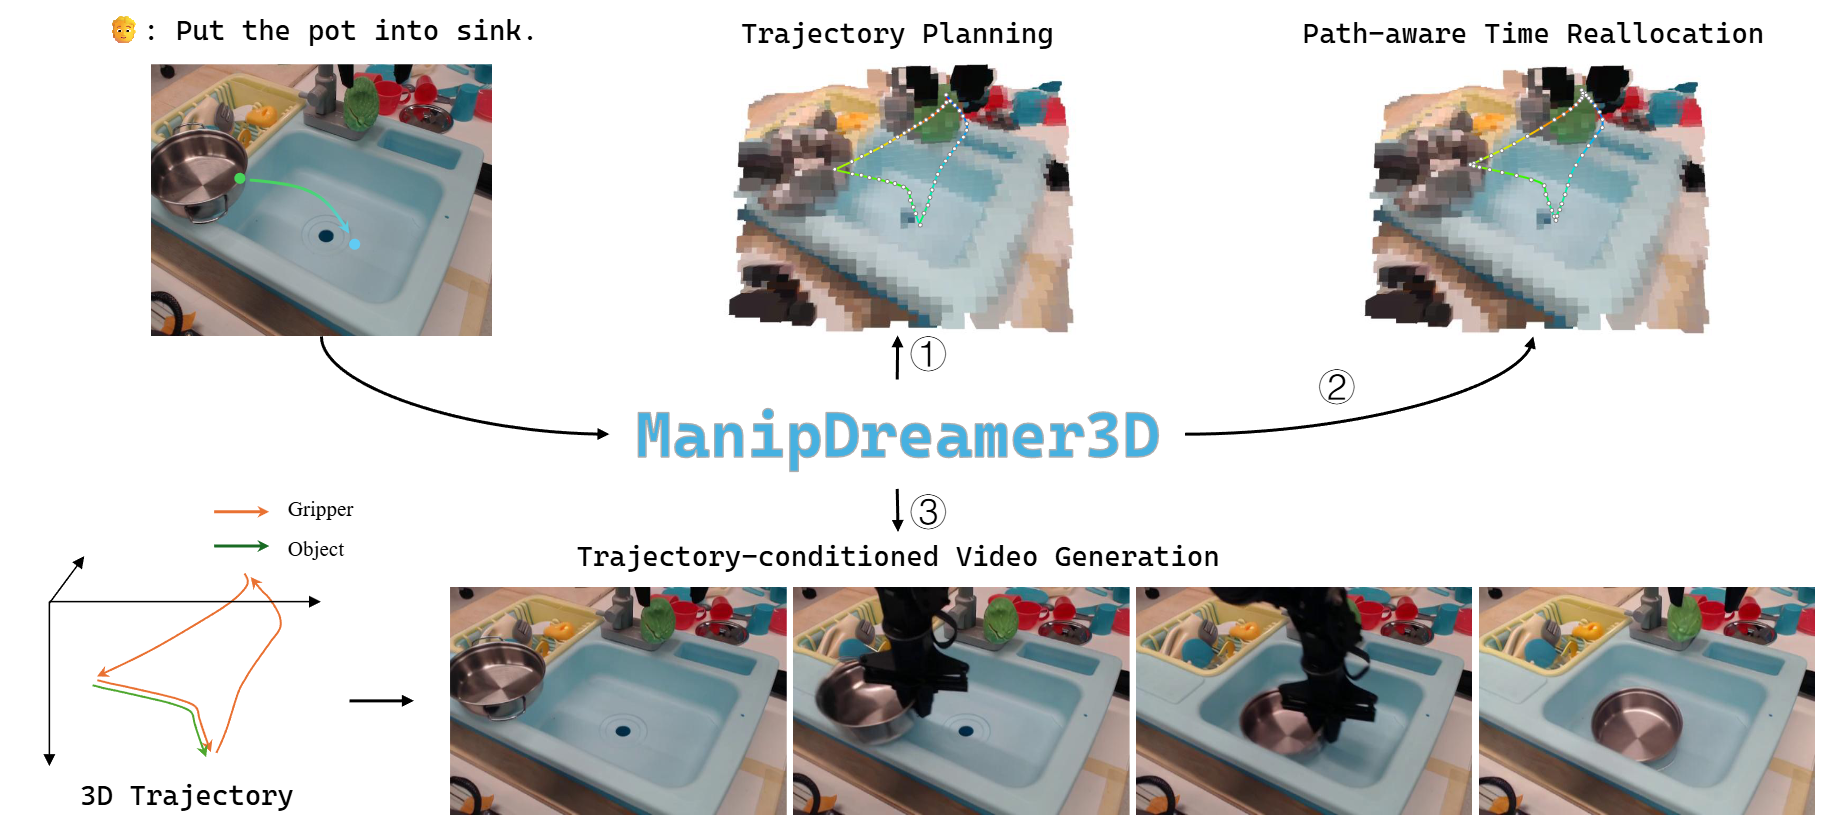
ManipDreamer3DSynthesizing plausible robotic manipulation videos with occupancy-aware 3D trajectories.
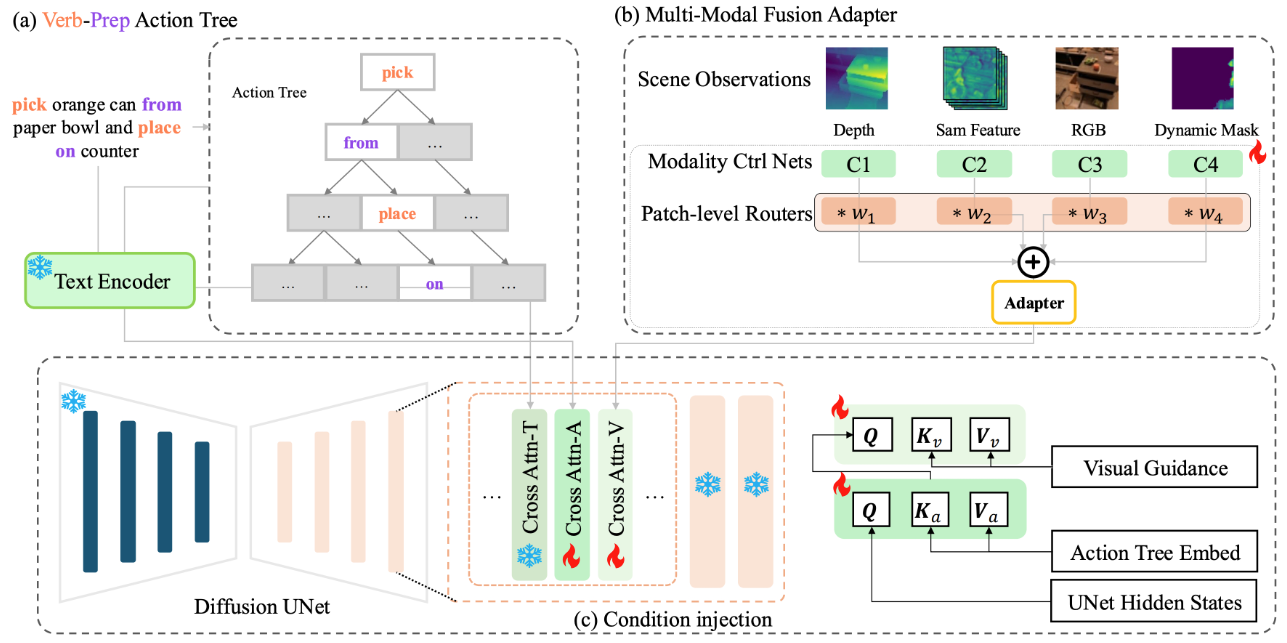
ManipDreamerBoosting manipulation world models with action trees and visual guidance.
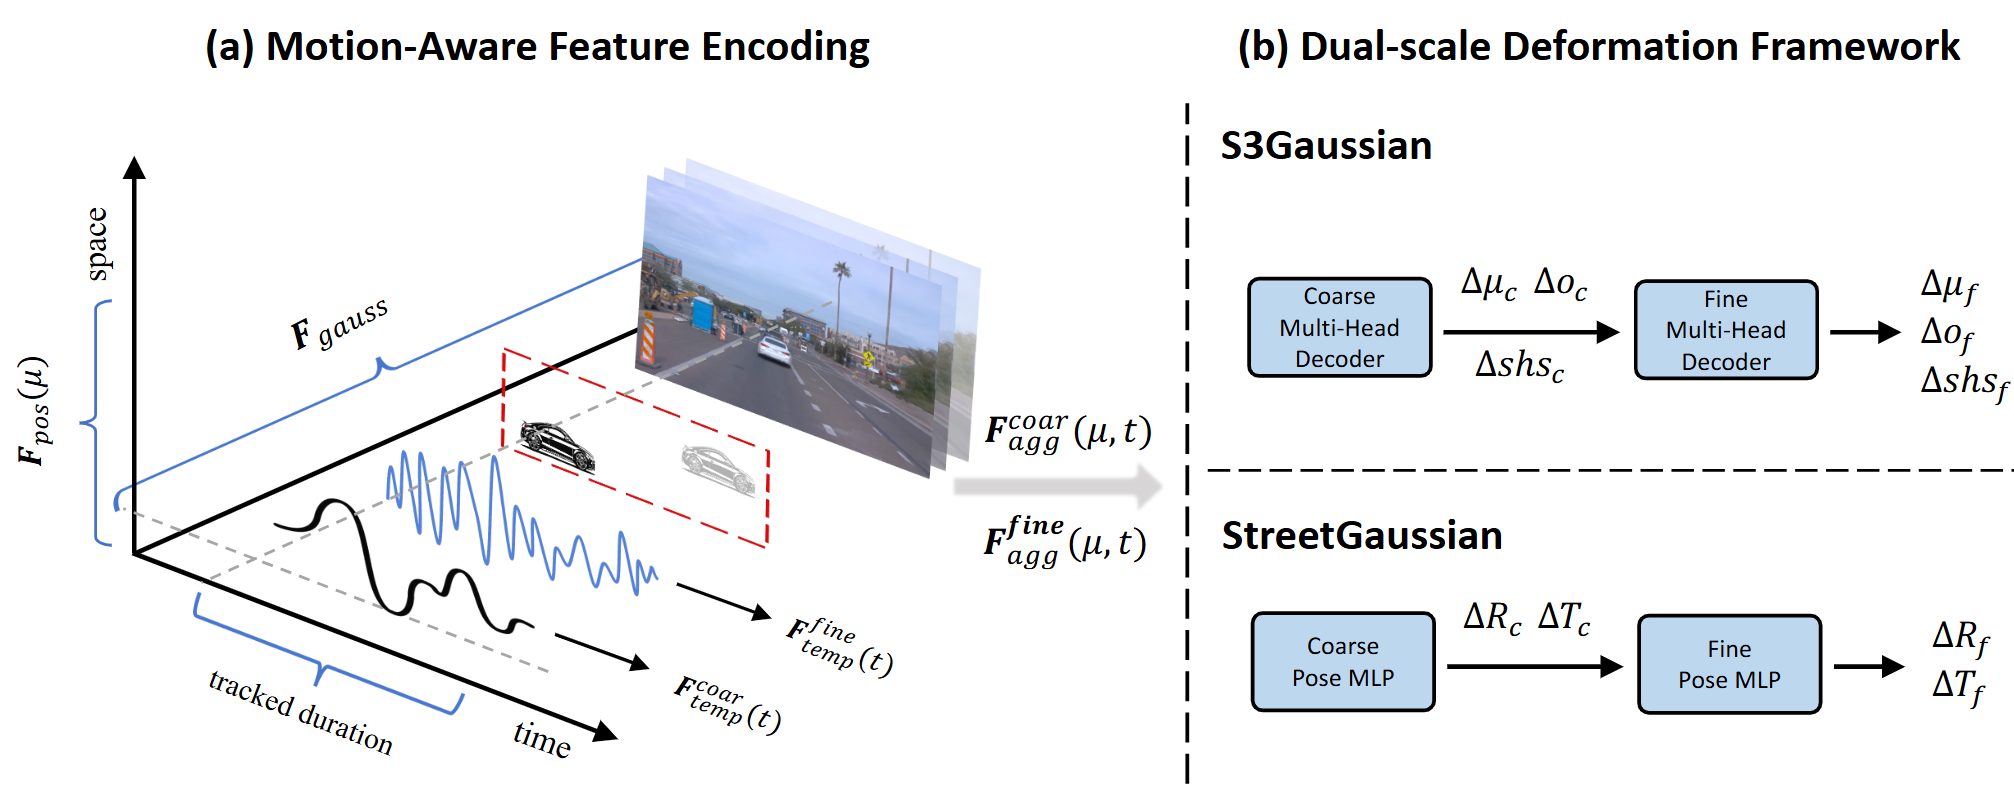
S3GaussianSelf-supervised street Gaussians for decomposing dynamic and static driving scenes.
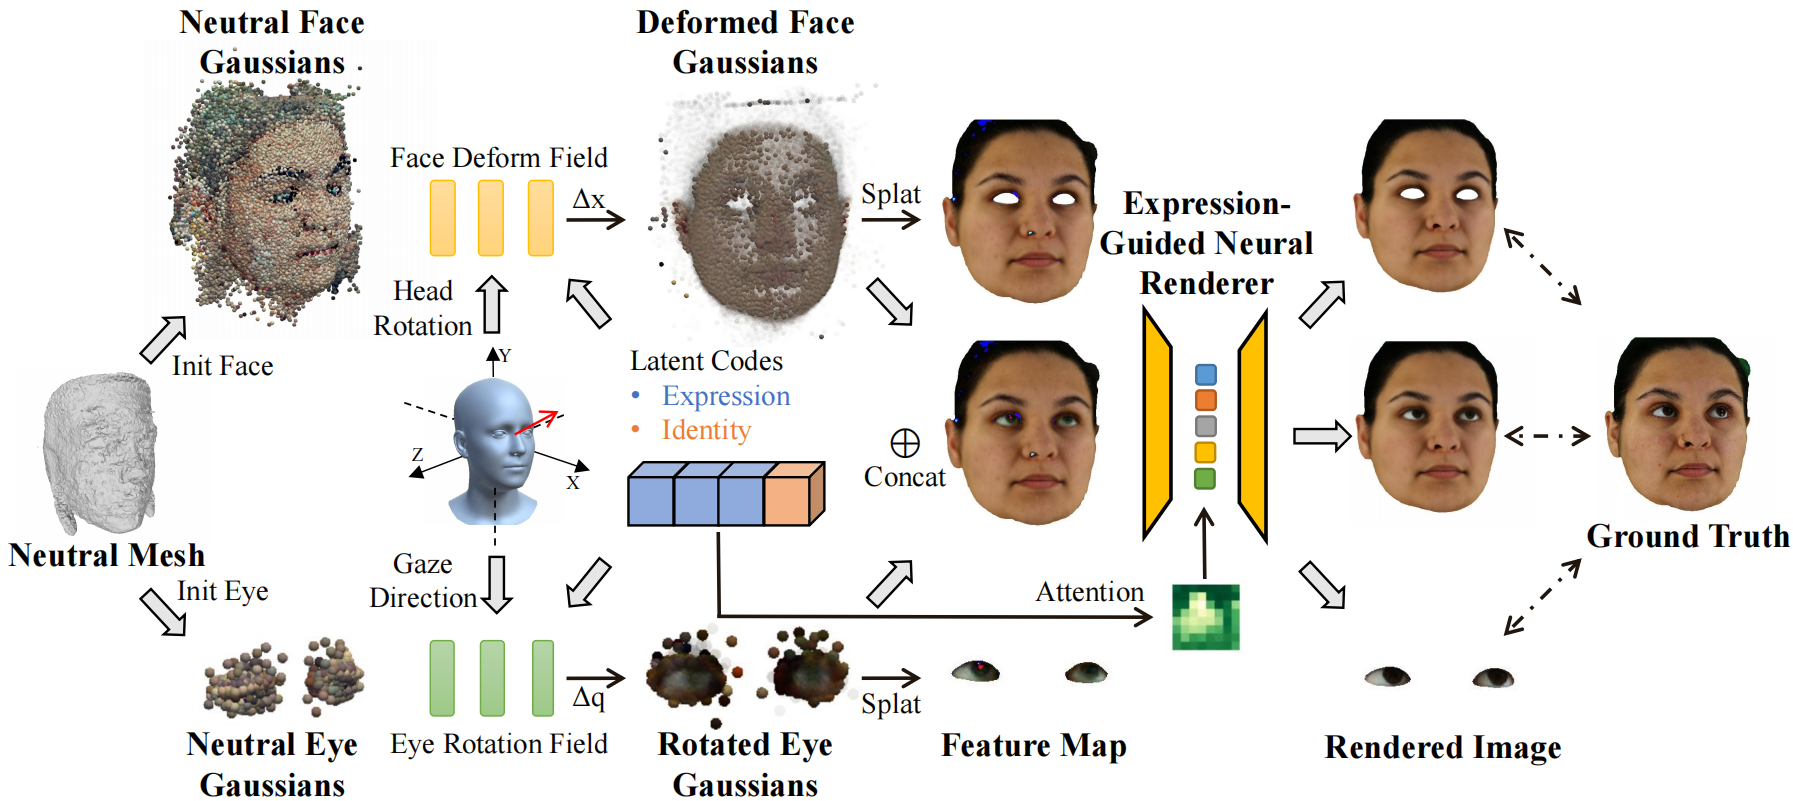
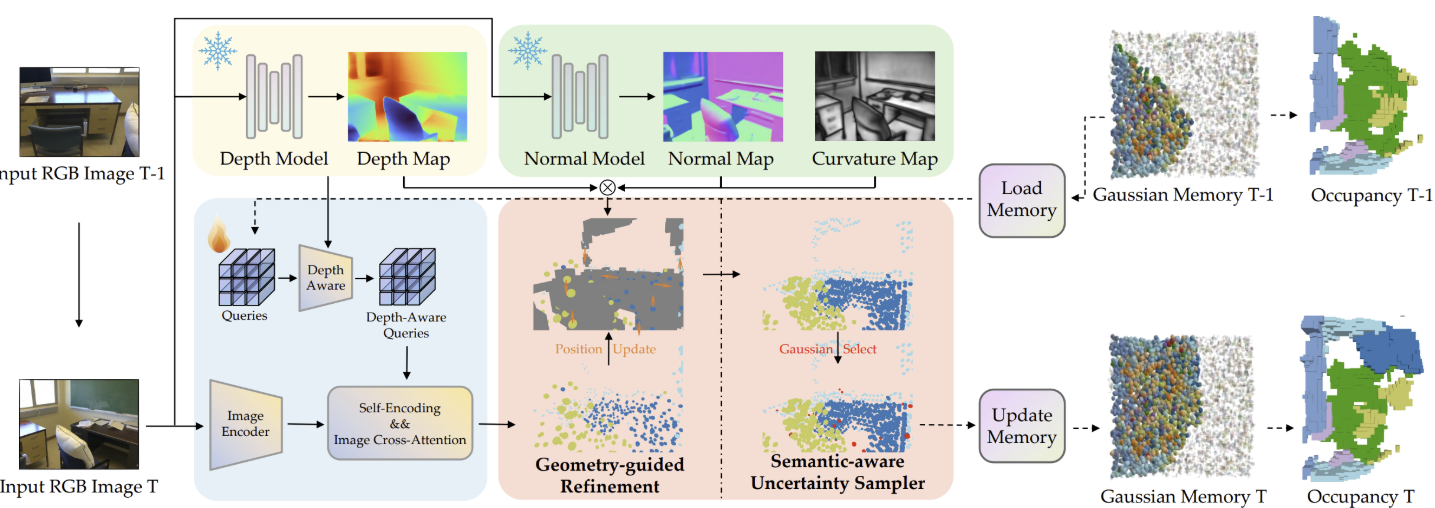
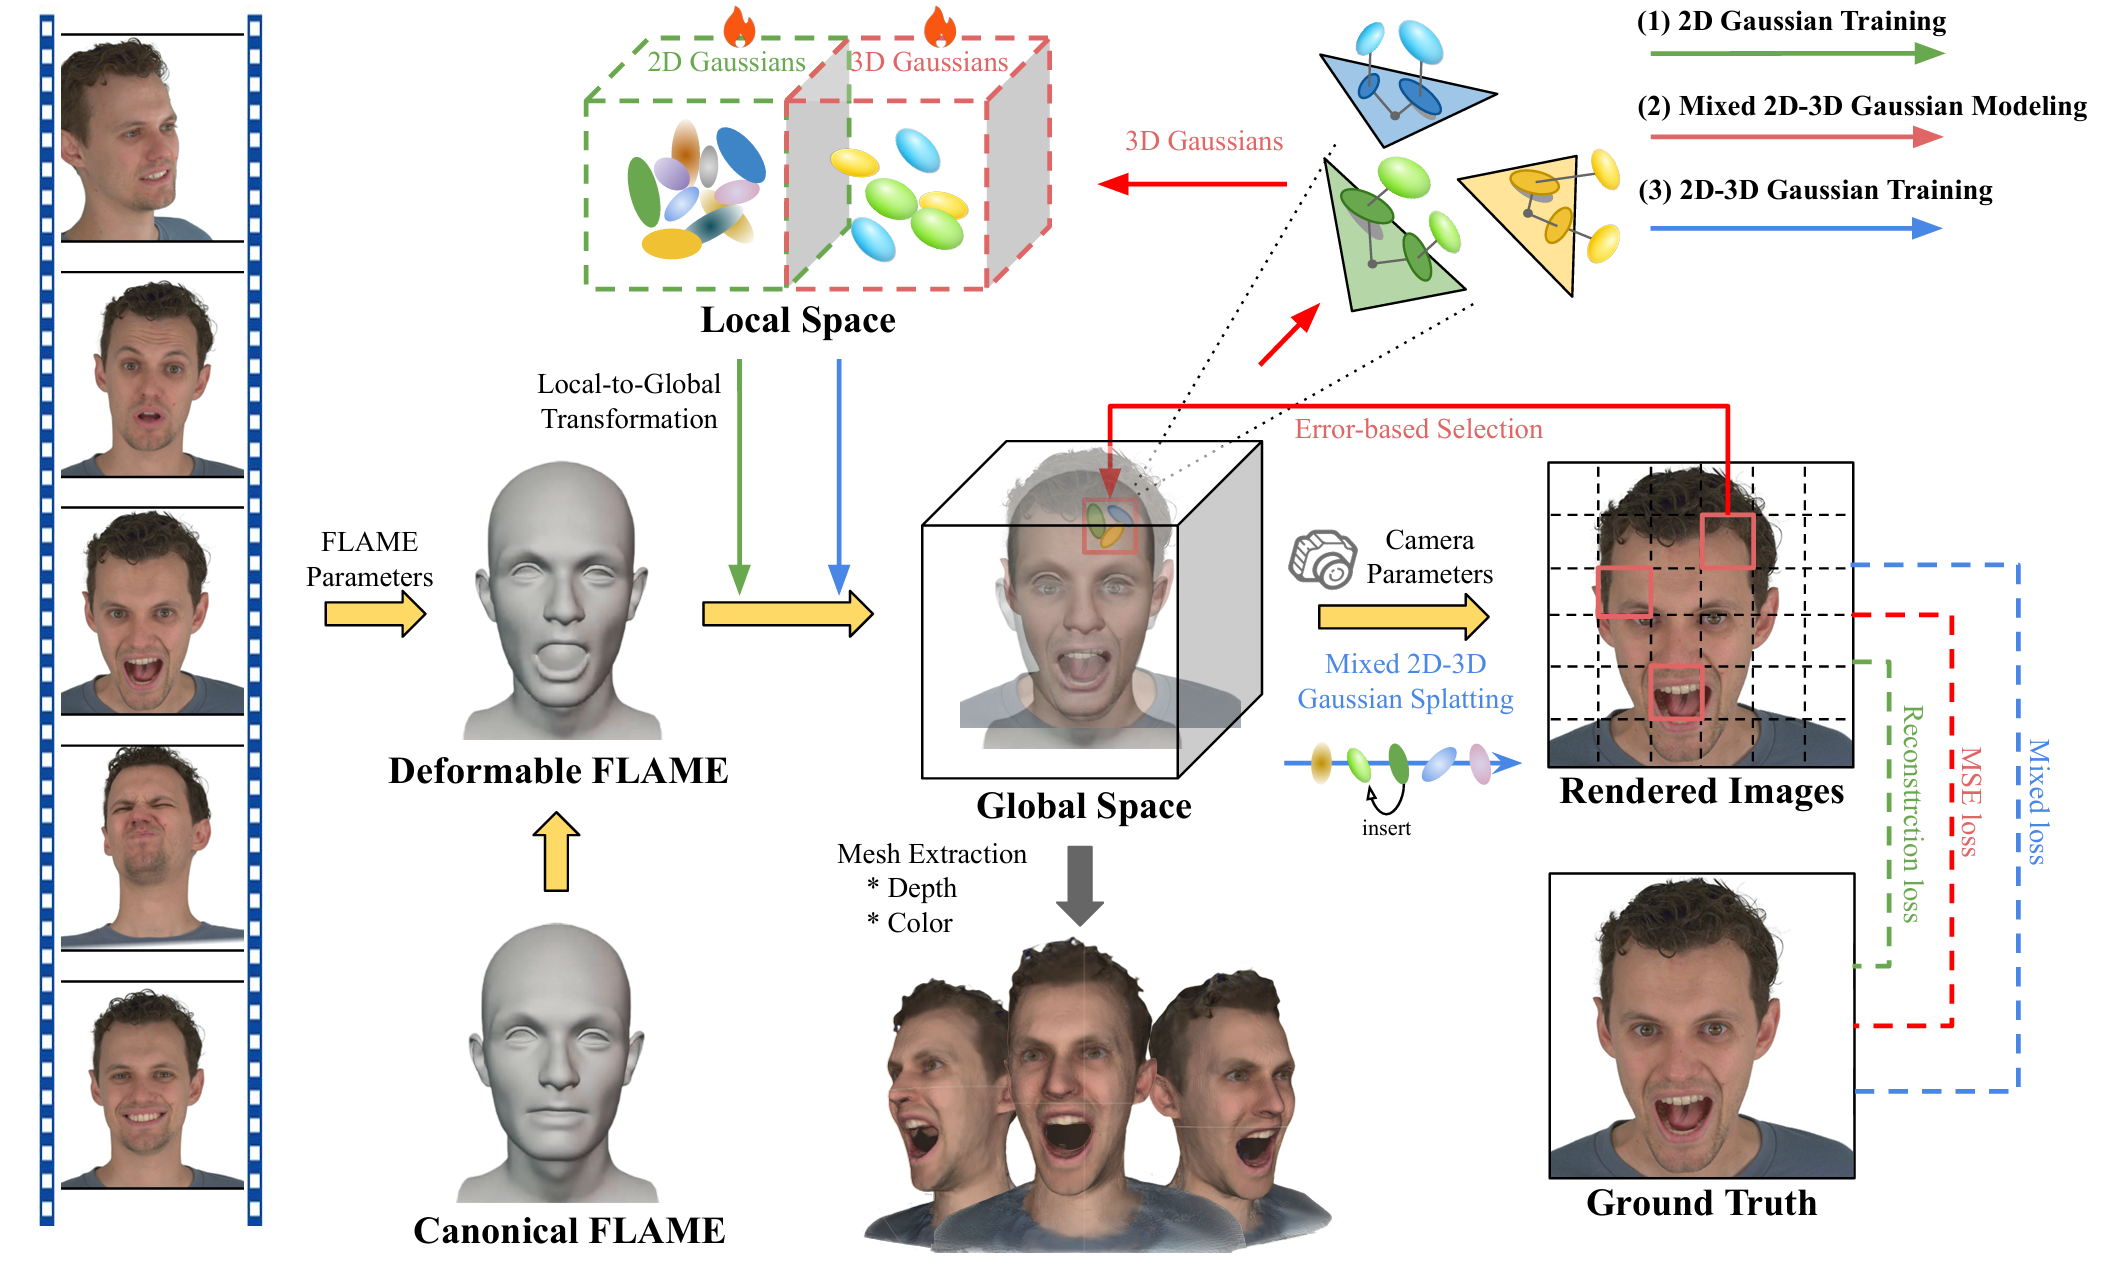
EmbodiedOcc++Geometry-aware and uncertainty-aware 3D occupancy prediction for embodied agents. MixedGaussianAvatarRealistically and geometrically accurate head avatars with mixed 2D–3D Gaussians.
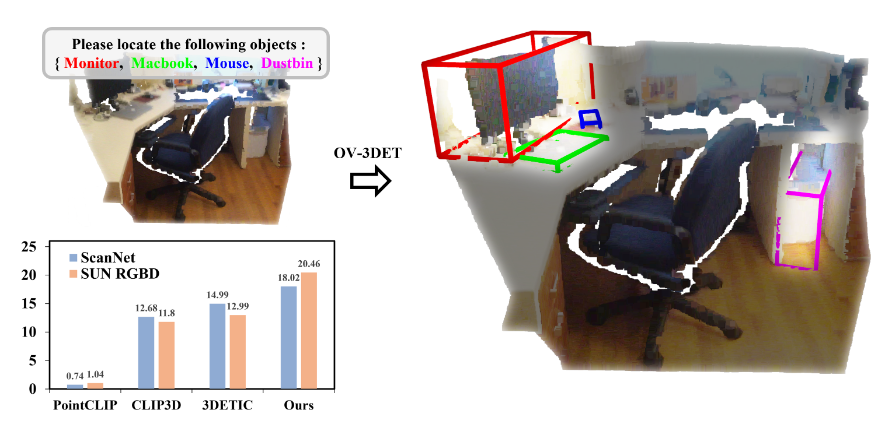
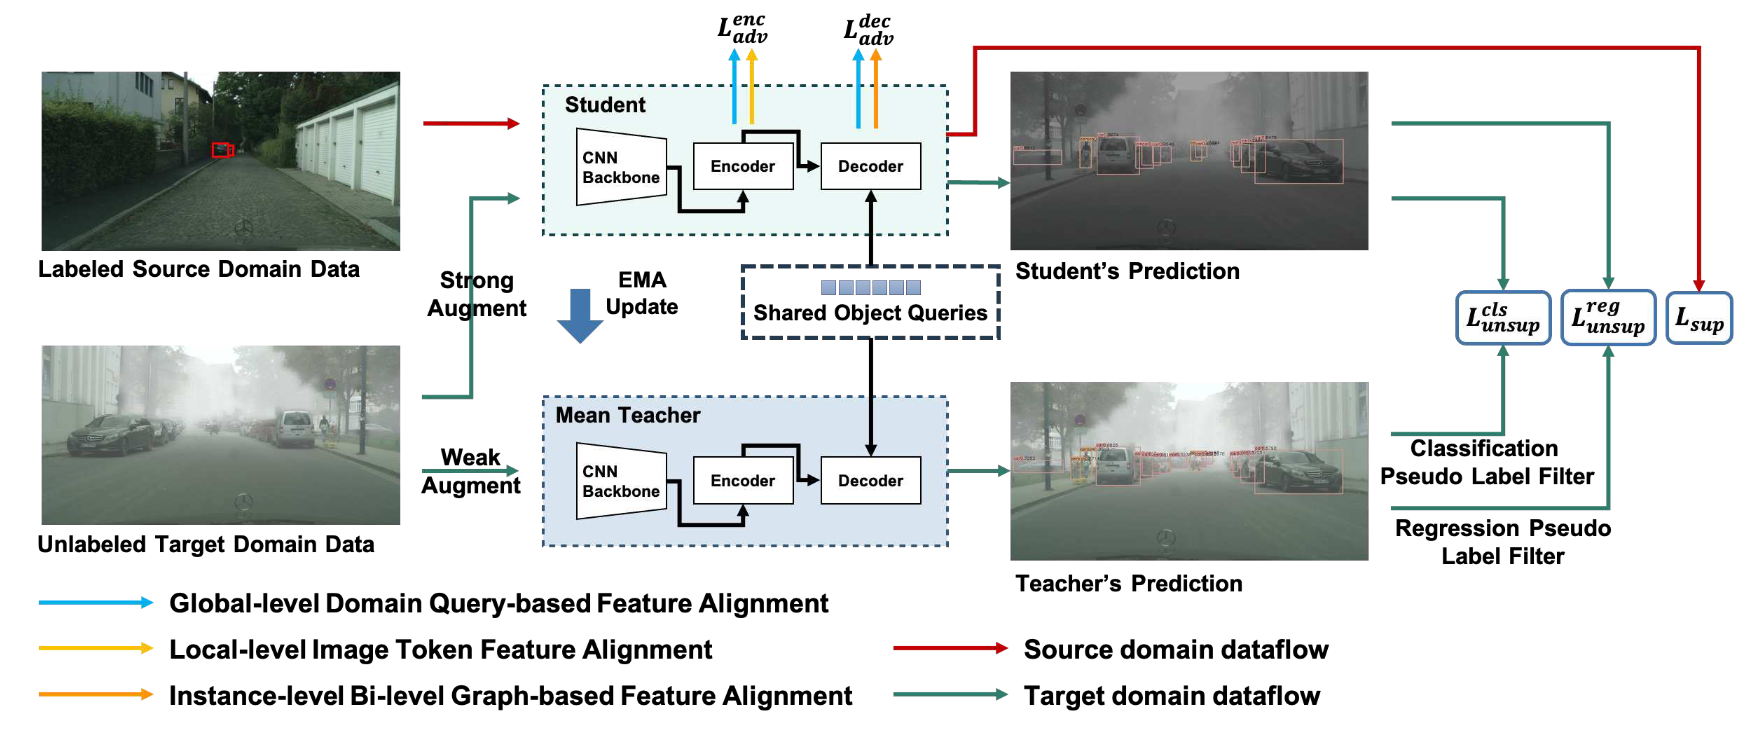
Open-Vocabulary 3D DetectionOpen-vocabulary point-cloud object detection without 3D annotation.
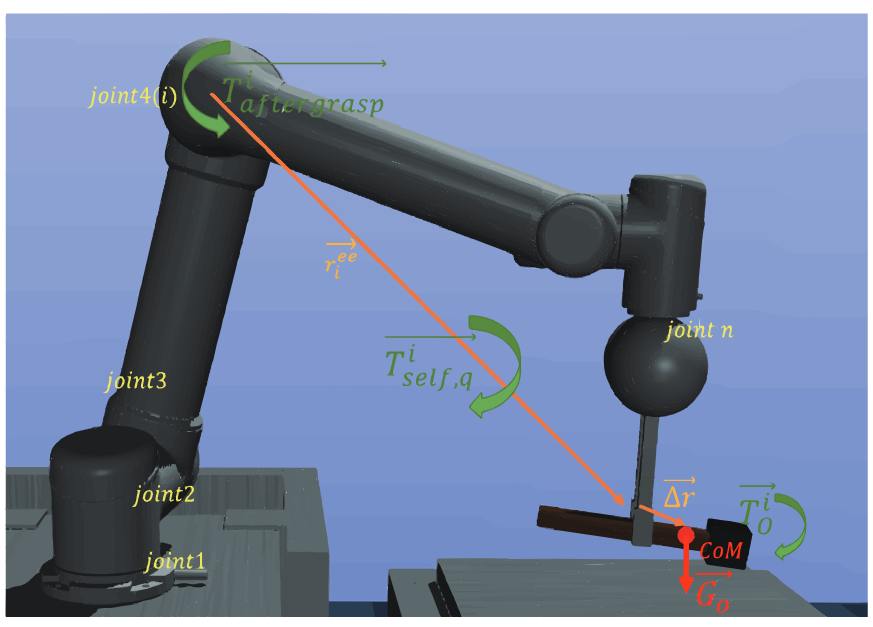
Robust Grasp Pose AdaptationCenter-of-mass-based grasp adaptation using RGB-D and force/torque sensing.
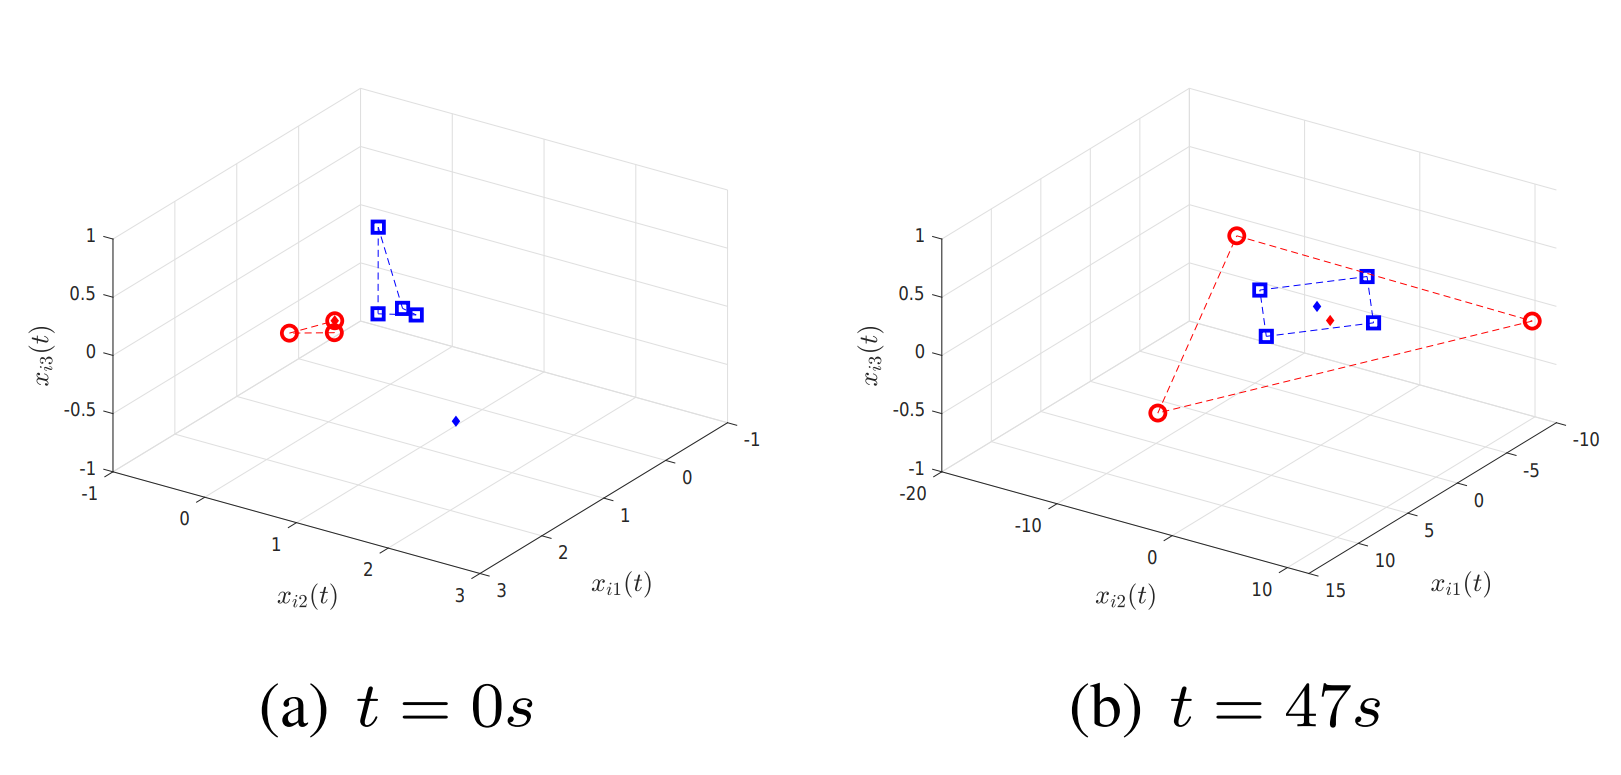
Multi-agent Formation TrackingTime-varying formation tracking for heterogeneous multi-agent systems. |
|
Last updated: Nov. 2026
|